Why Serving 1,000 Fine-Tunes Doesn't Need 1,000 GPUs
Автор: SkildCore
Загружено: 2026-10-19
Просмотров: 8
Описание:
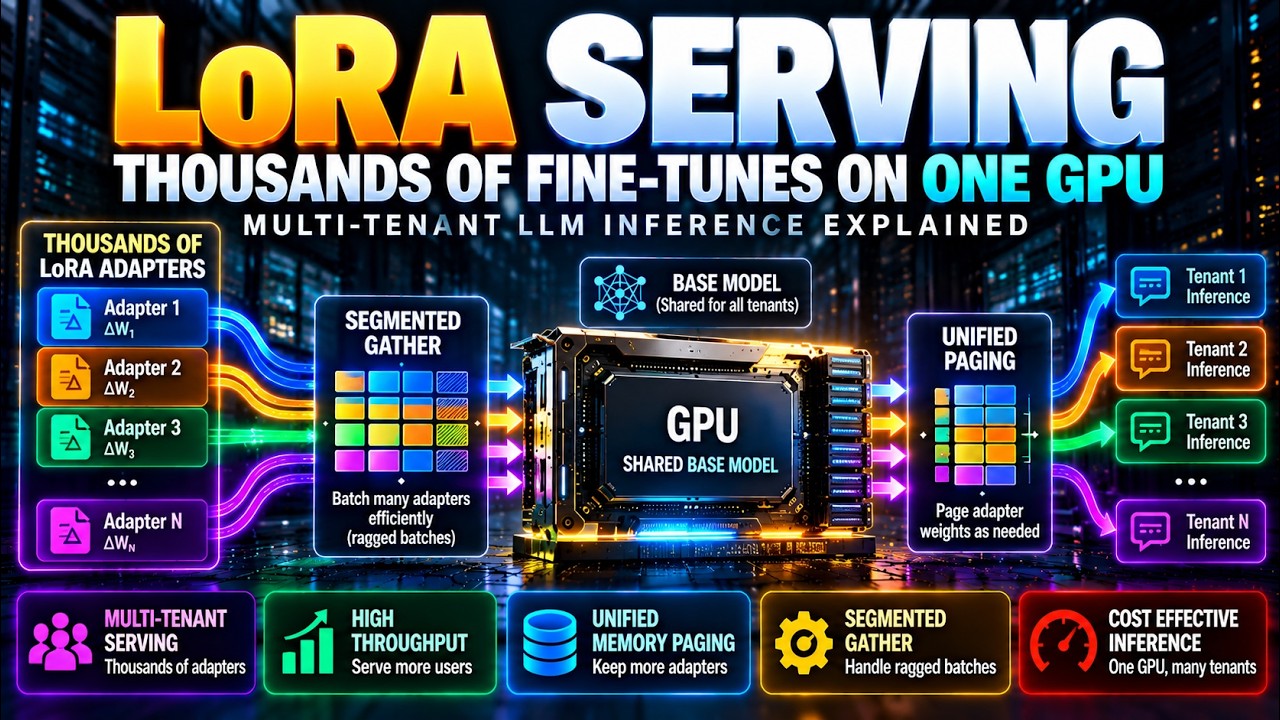
🚀 How can one GPU serve thousands of fine-tuned LLM adapters without loading a separate model for every tenant?
In this Skildcore deep dive, we explore multi-tenant LoRA serving, the mathematics behind low-rank adapters, and the GPU architecture required to make adapter inference scalable.
We break down why two obvious approaches fail, how segmented gather handles ragged adapter workloads, and why unified paging and GPU memory management matter as tenant counts grow.
🔥 WHAT YOU'LL LEARN
• How LoRA modifies model weights using low-rank matrices
• Why serving thousands of adapters is a GPU systems problem
• Shared base models vs tenant-specific adapter weights
• Segmented gather and ragged GPU computation
• Performance characteristics of serving 100 adapters on an A100
• Unified memory pools and adapter weight paging
• Why GPU memory fragmentation matters
• Throughput and latency trade-offs in multi-tenant inference
• Practical lessons for production LoRA serving
⏱️ CHAPTERS
00:00 A Thousand Fine-Tunes, One GPU
00:30 The Mathematics of a LoRA Adapter
01:30 Two Obvious Serving Approaches — Both Fail
02:00 Split Every Layer into Two Paths
02:30 Segmented Gather: Batch the Ragged Half
03:30 100 Adapters, 200 MiB, One A100
04:30 Unify the Pools, Page What's Left
05:00 Page Tables for Weights, Not Just Caches
06:00 Throughput Stays Flat as Tenants Pile Up
06:30 Nothing Here Is Free
07:30 It Shipped — Final Architecture
💡 The key insight: Efficient multi-tenant LoRA serving depends on sharing the base model, batching adapter computation intelligently, and managing GPU memory without treating every fine-tune as a separate model deployment.
Subscribe to Skildcore for technical deep dives into GPU architecture, LLM inference, distributed systems, and production AI infrastructure.
#LoRA #LLMInference #GPUServing
Повторяем попытку...
Доступные форматы для скачивания:
Скачать видео
-
Информация по загрузке: