Видео с ютуба Skildcore

The SSM Layer Nobody Made Fast (Until Now): ReplaySSM Explained

Bolt-On vs Native Drafters: Medusa, EAGLE, and MiniMax DSpark Architecture

700 tok/s on a 2.8 Trillion Model: The 92-Layer TPU Megakernel

How vLLM's NIXL Push Mode Cuts Disaggregated TTFT by 3× (RDMA Write Deep Dive)

How SGLang Fixed the Hybrid Attention Memory Cliff (Attention + Mamba Serving)

The 72-Hour Parity War: DeepSeek DeepInfer vs. vLLM vs. SGLang

Prefill vs Decode: Why LLM Inference Is So Slow (GPU Bottlenecks Explained)

The Green Dashboard Outage: Why Disaggregated LLMs Stall Over TCP

4.2x Faster Trillion-Parameter Inference: vLLM Day-0 Stack Breakdown

NVIDIA and AMD Just Shipped Custom Kernels for the Same Engine (On the Same Day)

Why LLMs Read 140 GB per Token — Speculative Decoding & Tree Attention

Why Remote KV Caching Slowed Down Our LLM (The 2.53 GB/s Break-Even Rule)

How vLLM's Megakernel Cuts MoE Decode Latency by 50% (Kimi K3 Breakdown)

Inside DeepSeek's 155 Trillion Token Engine: What They Didn't Open Source

Why a 1-Trillion Parameter Model Dies at the Optimizer (Muon vs AdamW)
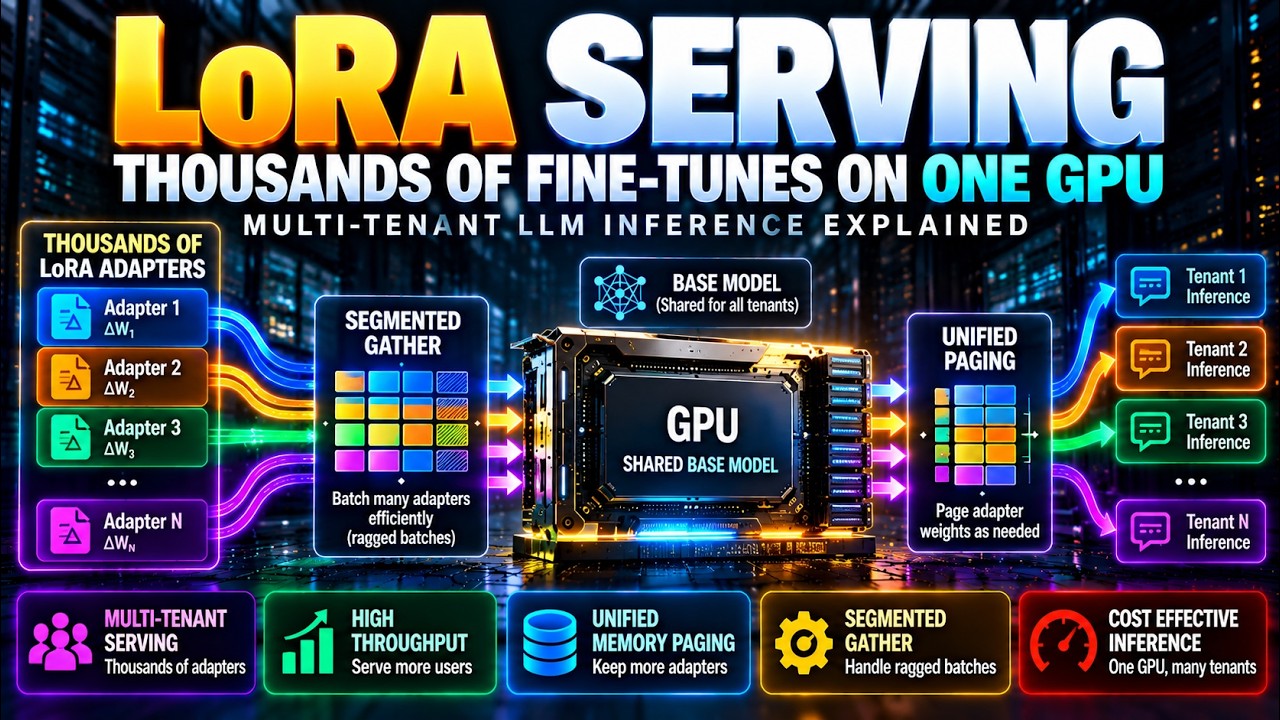
Why Serving 1,000 Fine-Tunes Doesn't Need 1,000 GPUs

How LLMs Generate Tokens Faster: Speculative Decoding + Tree Attention

How Context Parallelism Splits Long Sequences Across GPUs

Why Modern "Path Traced" Games Are 99% Hallucinated Rays