AI Speed Test: Benchmarking a 120B Model on Dual NVIDIA RTX A6000 GPUs
Автор: Ingmar Stapel
Загружено: 2025-09-08
Просмотров: 323
Описание:
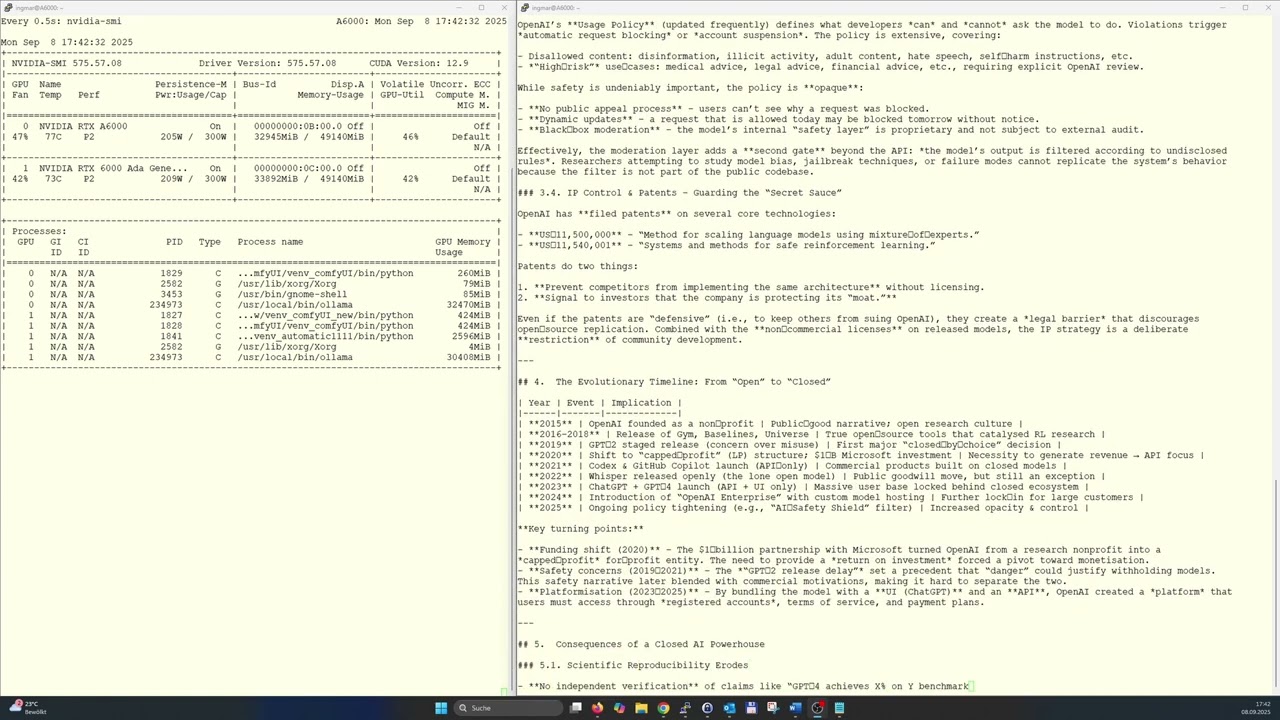
In this video, I am putting my local AI workshop to the test! I'll run a comprehensive benchmark to measure the real-world performance of my hardware setup when running a massive 120 billion parameter language model.
The key metric I am focusing on is inference speed, measured in tokens per second (tokens/s), which is crucial for a smooth and responsive AI experience. Join me as I find out how my system, powered by two NVIDIA RTX A6000 GPUs, handles the challenge.
My Testing Setup:
Model: gpt-oss:120b
Tool: Ollama (with the --verbose parameter for detailed stats)
Hardware: 2x NVIDIA RTX A6000
Prompt: "Write a Long post, why 'OpenAI' is 'closed AI'."
Повторяем попытку...
Доступные форматы для скачивания:
Скачать видео
-
Информация по загрузке: